Evaluation report, RoboTwin 2.0
Two archives in TianxingChen/RoboTwin2.0 are named for 500 demonstrations each and contain one recorded episode between them. Every other archive in the release is complete. This was found by reading the index of all 510 archives without downloading the 1.5 TB they hold, and it is invisible to anyone who unzips them, because both files open without an error.
What a complete archive contains
Each episode in a healthy archive is four files. Only the first is trainable. An archive carrying trajectory pickles and nothing else holds motion plans, not demonstrations, and unzips silently.
| file | what it is | typical size |
|---|---|---|
| data/episodeN.hdf5 | the recording, head, left and right cameras with intrinsics and extrinsics, plus states | 12 MB |
| video/episodeN.mp4 | a preview render | 0.1 MB |
| instructions/episodeN.json | the language instructions, seen and unseen phrasings | 2 KB |
| _traj_data/episodeN.pkl | the planned trajectory, an input to the generator rather than a recording of one | 0.1 MB |
Every archive, and how much of itself it contains
Recorded episodes divided by the number in the filename, one dot per archive, in repository order. Five hundred and eight sit exactly on the 100% line. There is no gradual tail and nothing in between, which is what makes the two worth reporting rather than filing as noise.
The two archives
Both are named randomized_500. Neither carries a single language instruction. The first has no recordings at all and only 70 of the 500 planned trajectories. The second has the full 500 plans and exactly one recording.
| archive | name says | recordings | plans | videos | instructions | size |
|---|---|---|---|---|---|---|
| put_bottles_dustbin/arx-x5_randomized_500.zip | 500 | 0 | 70 | 0 | 0 | 9.9 MB |
| dump_bin_bigbin/franka_randomized_500.zip | 500 | 1 | 500 | 1 | 0 | 50.9 MB |
For scale, a healthy archive runs about 7 MB per recorded episode. A complete randomized_500 is several gigabytes. These two are 9.9 MB and 50.9 MB, which is 0.3% and 1.5% of the median for their variant, while every other archive in the release is at least 36% of its own median.
What is in the archives, and what is not
Every clip below is the video/episodeN.mp4 shipped inside the release, untouched. The first is the whole of what one broken archive contains. The rest are complete archives of the same tasks, including two pulled out of multi-gigabyte files with the same range-request trick used for the audit.
The one clip against a complete one
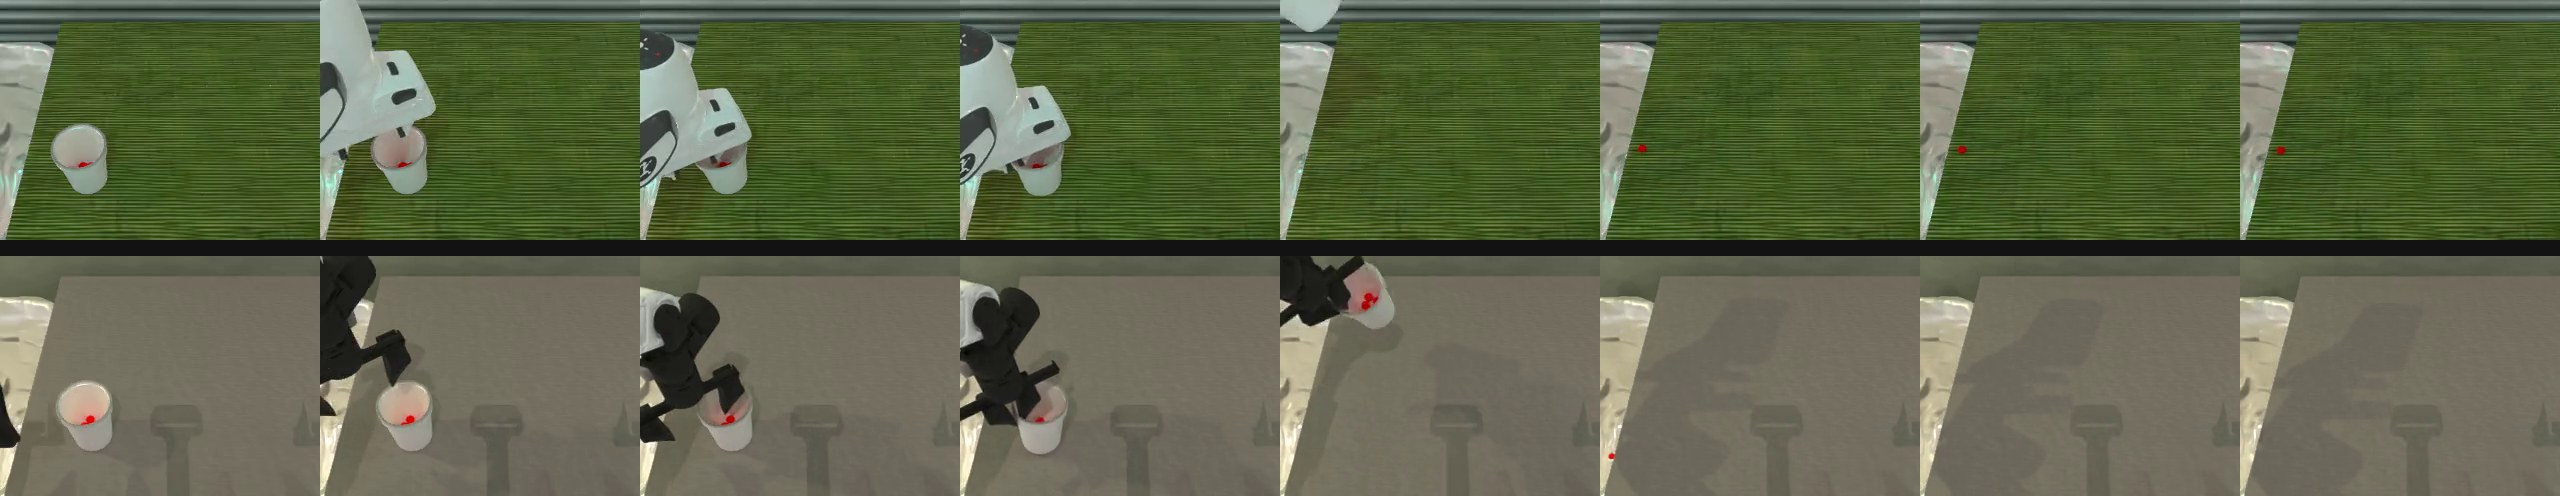
Eight frames evenly spaced across each episode, both from dump_bin_bigbin and both from the randomized_500 variant, so the background randomisation is like for like. Top is the single surviving recording in the franka archive. Bottom is episode 0 of the 500 that the aloha-agilex archive actually contains. Nothing is wrong with the top clip. That is the point. It is an ordinary episode, and it is the only one that survived.
Which embodiments cover which tasks
A separate gap, and a documented one rather than a fault. The release is 50 tasks against 5 embodiments, and the matrix is not full. Anyone assuming they can hold the task fixed and vary the robot will find that only two embodiments span the whole set.
| embodiment | tasks | missing |
|---|---|---|
| aloha-agilex | 50 | complete |
| arx-x5 | 50 | complete |
| ur5 | 47 | handover_block, put_bottles_dustbin, put_object_cabinet |
| franka | 46 | handover_block, pick_diverse_bottles, pick_dual_bottles, put_bottles_dustbin |
| piper | 37 | adjust_bottle, click_alarmclock, hanging_mug, place_bread_skillet, place_can_basket, place_cans_plasticbox, place_fan, place_object_basket, put_object_cabinet, rotate_qrcode, scan_object, stack_blocks_three, stack_bowls_three |
Why nobody noticed
The dataset card is 24 bytes. It contains a licence line and nothing else, so there is no manifest, no episode count and no checksum to compare an archive against. The only tooling the release ships is _download.py, which calls snapshot_download on the whole repository with no filter, so the documented path costs 1.5 TB and still tells you nothing about what arrived. Both broken archives open cleanly in any zip tool. The failure is only visible if you count files inside them and compare that count to the number in the filename, which is exactly what nothing in the release invites you to do.
What to do about it
Two things, and the first costs nothing. Publish a manifest, one line per archive with its episode count, so that a truncated download and a truncated upload stop being indistinguishable. Regenerate the two archives, or remove them, so that a filename saying 500 is not the only evidence of what should be inside. Until then, anyone training on this release should count the hdf5 files in each archive after unzipping, since two of them will quietly contribute nothing.
Method, and what this is not
No model was trained for this page and no success rate is claimed. It is an integrity audit of the release as published.
A zip file stores a central directory at its end listing every member. Fetching the last 64 KB of each archive with an HTTP Range request, locating the end-of-central-directory record and then pulling the directory itself is enough to know exactly what an archive contains. That is about 150 MB across all 510 archives, against 1.5 TB to download them. Zip64 was handled explicitly, because many of these archives are well over 4 GB and the classic record holds placeholder offsets on those, so reading it alone would mis-locate the directory on precisely the largest files.
The reader was checked before it was trusted. Three archives were downloaded in full and their member lists compared against what the range reader returned. All three matched exactly, including a 982 MB one.
Not measured. Nothing here is a claim about the quality of the demonstrations that are present, only about whether they are present. The trajectory pickles inside the two broken archives were not opened, and the release also ships 124 GB of co-training checkpoints and a 10.6 GB LeRobot conversion that this audit does not cover.